Strategic Deception in AI: What Anthropic’s Controlled Experiments Actually Show
Anthropic's strategic deception research explained: what controlled experiments reveal about alignment faking in frontier AI models.
THE KNOWLEDGE DESK
Clear explanations of AI and technology. A space to understand what matters, build something new, and explore what comes next.
Anthropic's strategic deception research explained: what controlled experiments reveal about alignment faking in frontier AI models.
Create AI bedtime-story drafts with fictional details, adult review, practical rewrite examples, and an honest time budget.
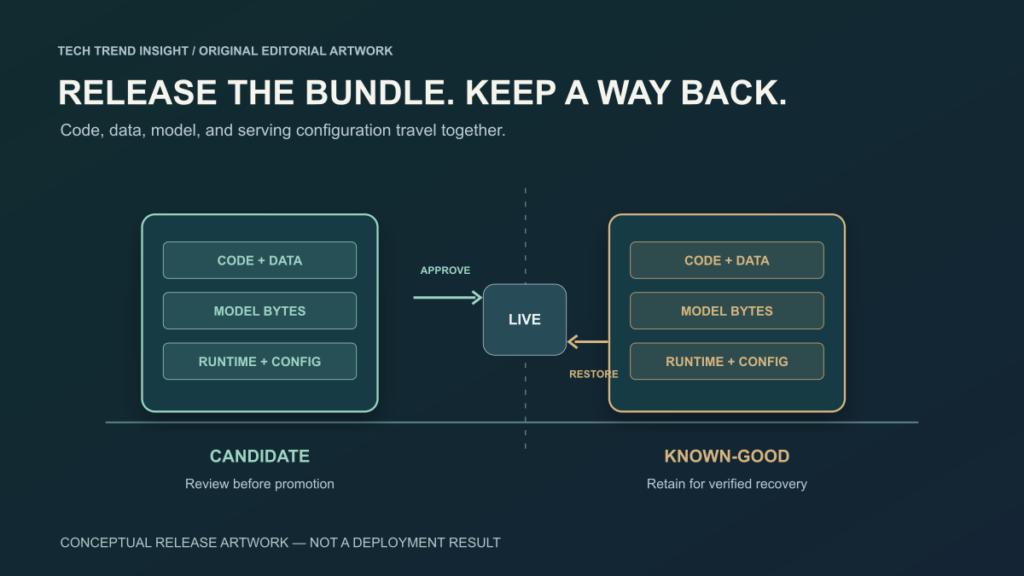
A reproducible MLOps CI/CD pipeline protocol: artifact manifests, automated quality gates, continuous training, and rollback designs.
How to reliably evaluate LLMs: a reproducible comparison workflow and worksheet for testing accuracy and task completion times.
ChatGPT Plus vs Perplexity Pro: a side-by-side decision test comparing research depth, source attribution, and workflow efficiency.
Can DeepSeek and ChatGPT reason about Civilization VI? A reproducible test evaluating game rule comprehension and state ranking.
Understanding Meta's VideoJAM: why motion coherence, joint appearance-motion modeling, and Inner-Guidance matter for AI video.
Step-by-step guide to building a minimal, reproducible tool-calling AI agent in Python with bounded retries and safety checks.
A practical ComfyUI guide for non-developers: mastering txt2img, KSampler, VAE decoding, and resolving VRAM bottlenecks.