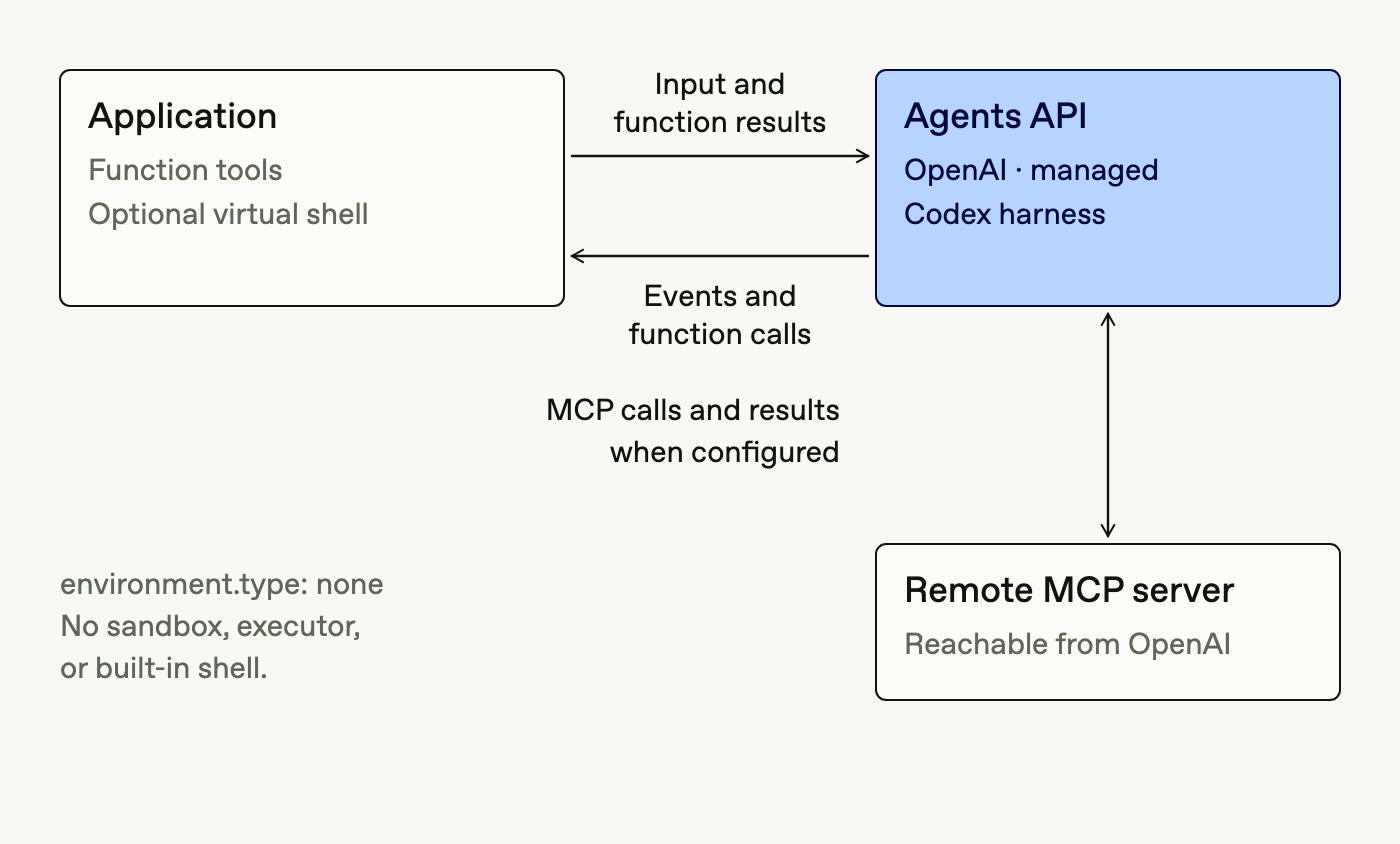
OpenAI’s Agents API removes substantial infrastructure work from long-running agent applications: OpenAI runs the Codex model-and-tool loop, retains durable session state, compacts context, coordinates subagents, and manages platform-level recovery. The application still chooses the agent’s tools and execution environment and remains responsible for product integration.
That division of labor is useful—but it does not make the managed session an authoritative record that an external business action committed correctly or exactly once.
Updated September 14, 2026
The defensible production architecture is to treat the Agents API as a managed harness for workflow continuity, not as a transaction coordinator, authorization service, or acceptance test. Use it where outcomes can be verified independently and consequential actions remain read-only, idempotent, reversible, or approval-gated. Retain an application-owned runtime when exact recovery order, storage location, independent reconciliation, or irreversible side effects require contracts the managed service does not meet.
📌 Key Takeaways
- OpenAI released the Agents API to all developers in public beta on September 10, 2026. The launch post says OpenAI is working toward general availability but provides no GA date.
- OpenAI manages the Codex harness, sessions, orchestration, context compaction, and recovery. The application supplies tools, handles application function calls, and chooses the execution environment.
- Self-hosting relocates command execution and working files—not the OpenAI-managed Agents API session.
- OpenAI documents that a mid-turn environment disconnect can fail a tool even when the turn completes. A terminal turn state must therefore not be treated as proof of an external business outcome.
/v1/agentsretains application state until deletion, is not eligible for Zero Data Retention, and currently supports Agents API state residency only in the United States.- Evaluate cost, reliability, and safety per externally verified task, not per API call or completed turn.
What the public beta promises
OpenAI announced the Agents API on September 10, 2026, describing it as a public-beta API for building cloud agents with the Codex harness managed by OpenAI. The company’s release notes independently label the release Beta and identify durable sessions, context compaction, recovery, custom tools, MCP servers, and hosted or externally supplied sandboxes as core features.
This is a separate runtime choice from the Agents SDK and Responses API. OpenAI’s agent-runtime comparison positions:
- the Agents API for long-running work where OpenAI runs the harness and stores session progress;
- the Agents SDK for applications that run the agent loop in their own process; and
- the Responses API for direct model integration or a custom application-owned loop.
The launch announcement says OpenAI will iterate during the public beta while working toward general availability. It does not announce a GA date.
Where hosted continuity stops
Durable sessions and context continuity
The Agents API overview defines a session as a durable instance of an agent working on tasks and responding to input. OpenAI retains session state so an application can continue across turns without reconstructing the entire conversation.
The managed harness can summarize earlier work as context grows, delegate independent tasks to subagents, connect to tools and MCP servers, and resume a session where it stopped. These are meaningful continuity features. They are not a substitute for validating the result against the system that owns the underlying business state.
Harness, environment, and application server
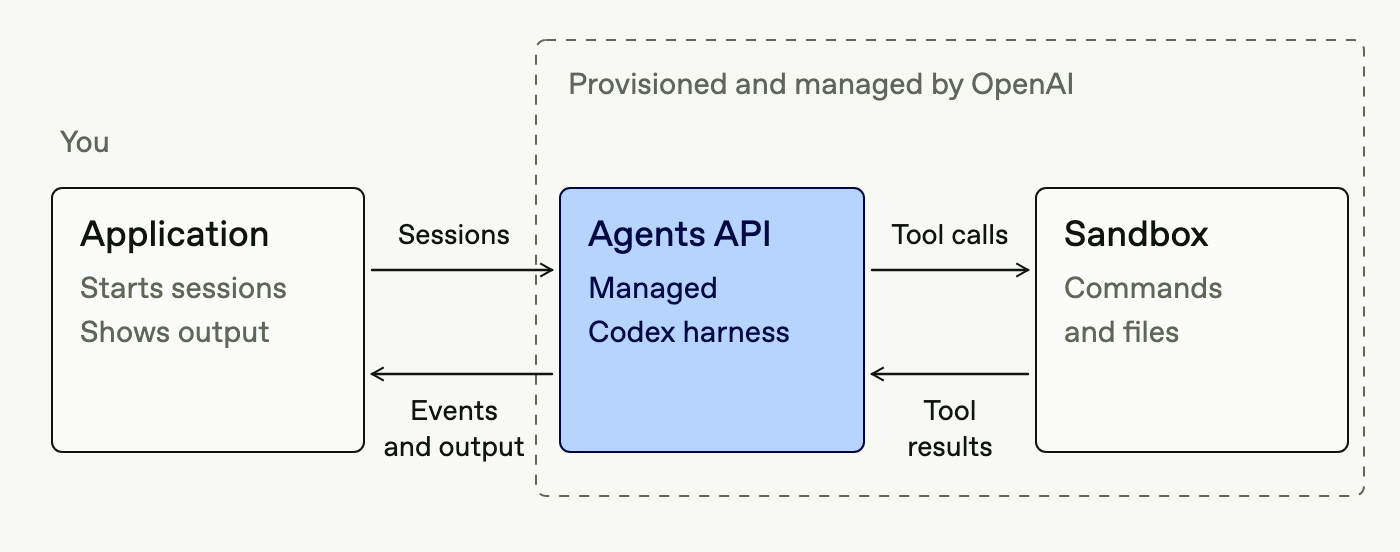
OpenAI’s architecture guide separates three components:
- Harness: the OpenAI-hosted Codex instance that runs the model-and-tool loop and maintains the session.
- Environment: the optional compute and filesystem on which commands run.
- Application server: the developer’s code that submits work, receives events, handles function tools, and manages a self-hosted environment’s lifecycle.
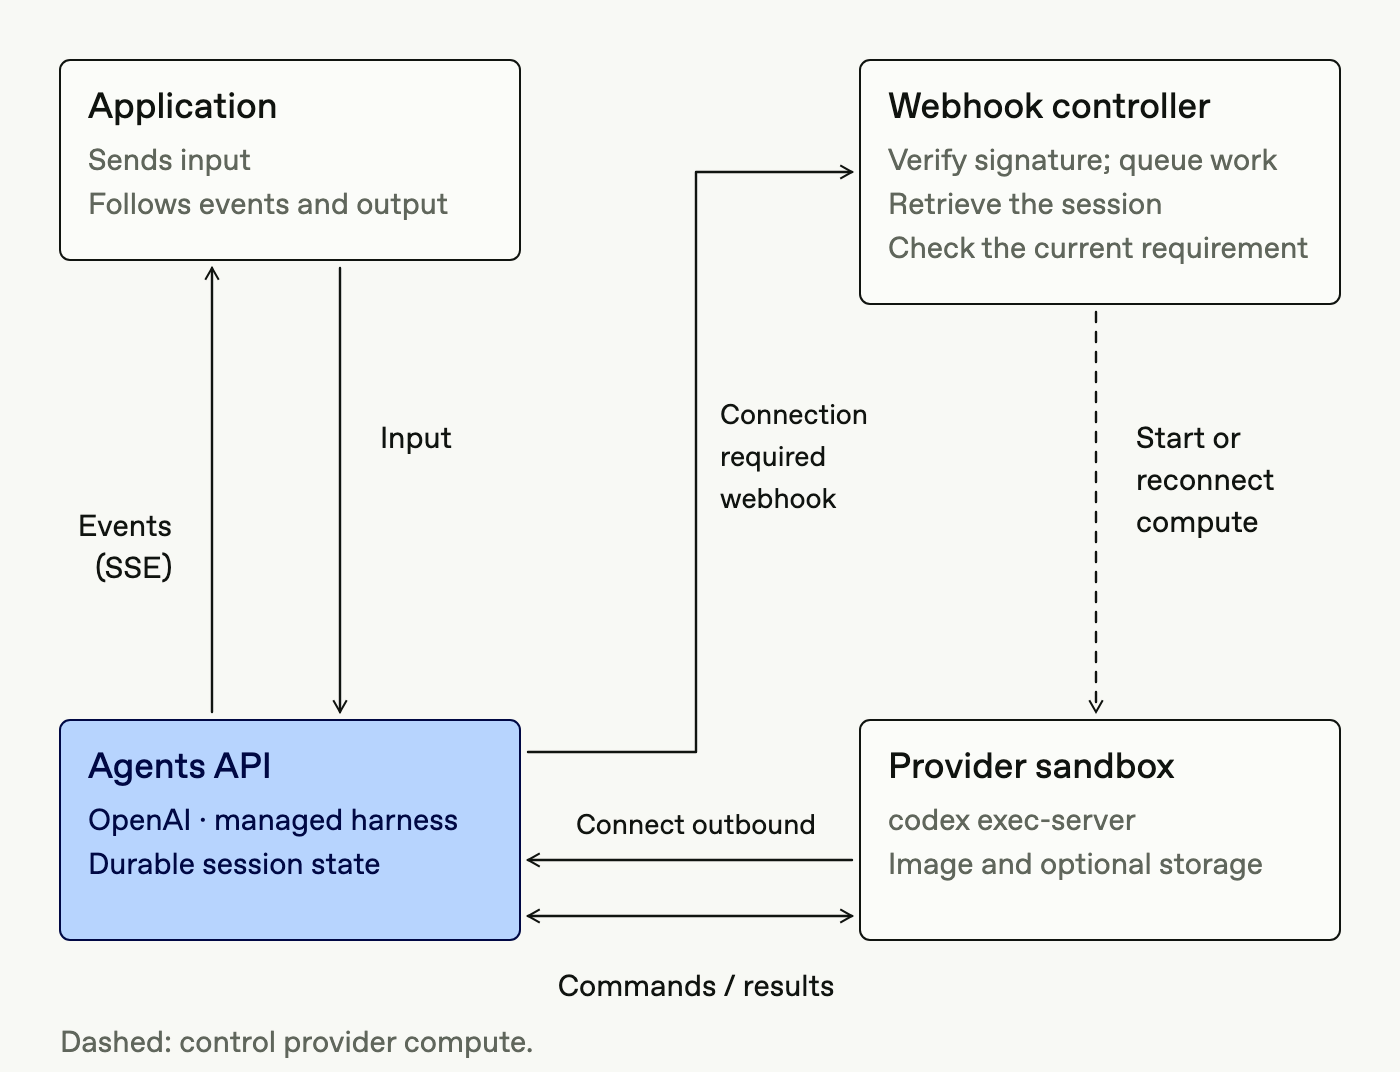
An agent can run with no environment, an OpenAI-hosted sandbox, or a self-hosted environment. In a self-hosted configuration, the application provisions compute, connects the executor, manages reconnection and shutdown, and preserves files when required.
Official architecture visual: the OpenAI-managed harness is separate from the developer application and the optional hosted or self-hosted execution environment. Reference: OpenAI Agents API architecture.
Tools and subagents
The managed harness can call remote MCP tools, request application function calls, use supported built-in tools, and delegate work to subagents. OpenAI’s documentation says each subagent receives its own context while the root agent coordinates results.
This is orchestration, not business authority. Tech Trend Insight’s architectural interpretation is that the application must still decide which tools exist, which credentials they receive, which tenant or user may invoke them, and what evidence is required before accepting a result. That follows from the documented application-controlled tool boundary; it is not an OpenAI transaction guarantee.
Application work that survives a resumed turn
The Agents API does not replace the surrounding controls normally required for consequential workflows:
- identity, tenant, and authorization checks;
- credential issuance, scope, rotation, and revocation;
- approval policy and separation of duties;
- idempotency keys and duplicate suppression;
- transaction commit, rollback, or compensation;
- output schemas and domain validation;
- reconciliation with authoritative systems;
- human review for ambiguous or high-impact outcomes;
- cleanup of customer-managed compute, files, and secrets.
The architecture documentation explicitly assigns task submission, event handling, application function execution, and self-hosted lifecycle management to application code. OpenAI’s Agents SDK documentation makes the alternative boundary equally clear: with the SDK, the developer’s server owns deployment, tool implementations, state storage, and approval decisions while the SDK runner performs the loop.
Three deployment choices, one proof boundary
| Option | Resumable state | Compute owner | Proof still owned by |
|---|---|---|---|
| Hosted sandbox | Managed session and turn state | OpenAI | Application: idempotency, reconciliation, and acceptance checks |
| Self-hosted environment | Agents API state remains managed | Developer | Application: network, credentials, side effects, and timeout handling |
| Agents SDK | Application or SDK-managed state | Application | Application: runner, storage, and recovery policy |
Read this as a responsibility map, not a performance benchmark. A resumed turn is useful only when the external effect can be reconciled.
The table combines OpenAI’s documented runtime boundaries with Tech Trend Insight’s engineering interpretation of where transaction and acceptance controls must live.
Editorial synthesis: OpenAI can own session continuity while the application retains authority over permissions, business-state transitions, external side effects, and acceptance. Based on the runtime comparison and architecture guide.
A completed turn can still hide a failed side effect
OpenAI’s self-hosted sandbox lifecycle documentation describes the most important production caveat: a mid-turn disconnect can fail a tool even if the turn completes. The disconnect does not automatically trigger a reconnection webhook or restart a killed command.
The same guide documents several additional boundaries:
- The API waits up to five minutes for an input-time executor connection.
- If that deadline expires, the submission fails.
- A late executor connection does not replay timed-out input.
- Recovery of pending input after an application process crash is not guaranteed.
- Reusing an environment ID does not restore files into replacement compute.
- Deleting a session neither stops a self-hosted environment nor emits a deletion webhook.
The five-minute figure is a connection deadline, not a maximum session duration or recovery SLA.
OpenAI does not state an exactly-once execution guarantee for external mutations in the reviewed documentation. More importantly, its documented disconnect and replay behavior makes such a guarantee unsafe to infer.
A turn.completed event should therefore be interpreted as “the harness completed the turn”, not “every intended external operation committed exactly once.” A deployment platform, payment processor, ticket system, database, or other authoritative service remains the source of truth for its own state.
Logs narrow uncertainty; they do not close it
The observability guide documents several useful surfaces:
- live session event streams;
- saved session items;
- public turn-list and turn-retrieval APIs;
- root-agent and subagent attribution through
subagent_id; - Platform dashboard logs and detailed traces;
- best-effort token usage for root and subagent turns.
The public beta also has documented limitations:
- as checked October 13, 2026, session trace export is documented as OTLP JSON through the customer API; verify organization enablement, project permissions, and all export pages;
- detailed dashboard trace endpoints are not a supported customer API;
- command-output truncation is not reported;
- usage may be
null, may change as accounting arrives, and is not a final bill; - Agents API usage fields do not expose a separate cache-write count.
These limitations do not make the runtime unobservable. They do mean that session telemetry alone should not be the acceptance oracle for a consequential action.
Self-hosted compute is not self-hosted session state
OpenAI’s data-controls table lists /v1/agents with:
- no use of API data for training by default;
- abuse-monitoring retention of up to 30 days under the default policy;
- application-state retention until deletion;
- no Zero Data Retention eligibility.
The Agents API overview further states that Agents API data residency currently supports only the United States and that selecting a self-hosted sandbox does not make the service ZDR-eligible.
A self-hosted environment can move commands, files, network access, and selected credentials into customer infrastructure. It does not move the managed harness or session state out of OpenAI’s service.
OpenAI’s session-management guide says deletion removes a session from the public API, while physical cleanup may continue asynchronously. Self-hosted compute must be stopped separately.
Use the API when the outcome is independently checkable
The strongest near-term use cases are evidence-heavy workloads with independently checkable outputs:
- repository investigation with reproducible tests or patches;
- incident-log analysis with cited source events;
- document and policy review with traceable references;
- draft recommendations reviewed before execution;
- data analysis against read-only or tightly scoped interfaces.
Ticket creation can be reasonable when the application uses an operation identifier or idempotency mechanism, checks the ticketing system for the authoritative result, constrains fields, and reconciles the returned record. The agent’s text saying “ticket created” is insufficient.
A worked recovery decision: a missing ticket receipt
Suppose a test workflow submits a ticket under operation ID incident-042, then loses its response. On resumption, the first question is not whether the agent can repeat the call. Query the ticket service for the operation identity and intended project. If exactly one matching ticket exists with the approved fields, record its identifier and accept the operation. If no record exists, follow the service’s documented retry semantics; if the lookup is incomplete or contradictory, keep the task unresolved.
This hypothetical case supplies an acceptance rule, not an exactly-once guarantee. It also exposes a useful failure test: deliberately interrupt the response after the test service commits, then confirm that recovery does not create a second ticket.
Deployments, payments, entitlement changes, destructive administration, and other irreversible operations should remain behind an application-owned authorization and transaction boundary. The agent may collect evidence, prepare a change, or request approval; the authoritative system should enforce identity, policy, commit status, and reconciliation.
For regulated workloads, the current /v1/agents retention, ZDR, and residency conditions may be disqualifying. Teams should evaluate the endpoint actually used—not extrapolate from data controls available to Responses API or other OpenAI services.
Price the verification path, not just the turn
OpenAI’s launch announcement says there is no additional Agents API platform fee during public beta. Model usage, OpenAI tools, hosted containers, and third-party services are billed separately.
As listed on the OpenAI API pricing page on September 14, 2026, hosted containers cost:
- $0.03 for 1 GB;
- $0.12 for 4 GB;
- $0.48 for 16 GB;
- $1.92 for 64 GB;
per 20-minute session per container. Eligible sessions are billed by the minute with a five-minute minimum. OpenAI defines these sizes as binary gigabytes.
Model and processing tier are separate billing choices. The documented model identifier is gpt-6-astra. Under Standard processing in the short-context tier, its published rates were $10.00 per million input tokens, $1.00 per million cached-input tokens, $12.50 per million cache-write tokens, and $50.00 per million output tokens. Long-context, Batch, Flex, Fast mode, and regional-processing configurations have different prices and conditions.
The useful denominator is not one API call. It is one externally verified task, including:
- root-agent and subagent model calls;
- reasoning and cache-write charges;
- tools and containers;
- failed attempts and retries;
- reviewer time;
- duplicate cleanup;
- recovery from uncertain outcomes;
- orphaned compute or file remediation.
Vendor testimonials in the launch announcement are reasons to test, not transferable benchmarks: their task sets, sample sizes, and evaluation methods are not disclosed.
Proposed validation (not run by Tech Trend Insight)
The following is a proposed evaluation design, not an account of firsthand testing.
- Runtimes: Agents API with self-hosted execution; Agents SDK with an application-owned runtime; Responses API with a custom loop.
- Controls: identical dated model snapshot, instructions, read-only tool schemas, container image, files, network policy, timeout policy, and external oracle. Disable live web access.
- Functional workload: 30 fixed tasks—10 repository investigations, 10 synthetic incident-log diagnoses, and 10 policy-document reviews.
- Functional repetitions: three runs per task on each of three runtimes: 30 × 3 × 3 = 270 proposed runs.
- Fault workload: 12 scripted conditions, including tool timeout, malformed output, duplicate webhook delivery, executor disconnect, worker restart, stale credentials, unavailable function handlers, and cleanup races.
- Fault repetitions: three repetitions per condition on each runtime: 12 × 3 × 3 = 108 proposed runs.
- Total proposed executions: 378.
- Measures: oracle-verified completion, unsupported claims, unauthorized calls, duplicate side effects, explicit handling of uncertain outcomes, recovery without manual state repair, wall-clock latency, root/subagent tokens, container minutes, provider cost, reviewer minutes, and orphaned compute or files.
- Proposed success criteria: zero unauthorized or duplicate actions; at least 95% of normal tasks pass the external oracle; at least 95% of transient-failure cases either recover or enter an explicit non-success state; no environment remains after required cleanup; and quality, p95 latency, cost, and reviewer effort remain within budgets fixed before testing.
- Reporting: publish task definitions, model and runtime versions, tool schemas, failure schedules, exclusions, and per-runtime distributions. Do not mix vendor testimonials into the experimental dataset.
The decision for engineering teams
Adopt selectively. Use the Agents API when durable managed orchestration removes meaningful operational work and completion can be proven outside the session through tests, schemas, immutable artifacts, or reconciliation against an authoritative system.
Adopt now: long-running repository, incident, document, or analytical workflows with externally checkable outputs and acceptable US-resident retained Agents API state.
Wait or retain an application-owned loop: workloads requiring ZDR, non-US Agents API state, application-defined recovery order, provider-neutral session storage, or transaction-grade handling of irreversible effects. Trace export is now documented, but an exported tool record still needs reconciliation with the external system’s outcome.
Evidence that would change this recommendation: GA with documented service commitments; broader Agents API residency or ZDR support; explicit replay or idempotency guarantees; validated trace completeness; independently reproduced recovery measurements; or internal validation demonstrating acceptable quality, latency, cost, cleanup, and side-effect safety.
Editorial decision flow: choose the managed runtime only after data-control, authorization, recoverability, observability, and external-verification gates pass. Documented inputs: OpenAI runtime guidance, sandbox lifecycle, and data controls.
Bottom line for adoption
The Agents API is a substantial reduction in agent-runtime plumbing, but managed state is not managed truth.
OpenAI can preserve what the agent was doing, coordinate its tools, and help the session resume. The surrounding application and authoritative business systems must still prove that the request was authorized, the intended action committed, the result is acceptable, and every associated resource was cleaned up.
Questions an implementation review should answer
Does a self-hosted Agents API environment keep the entire agent and session inside my infrastructure?
No. The self-hosted environment runs commands and holds its working files, but OpenAI still operates the Codex harness and retains Agents API session state. Self-hosting does not make /v1/agents ZDR-eligible or relocate that managed state outside the United States.
When should I choose the Agents API instead of the Agents SDK or Responses API?
Choose the Agents API when long-running sessions, context compaction, orchestration, and managed recovery remove meaningful operational burden. Choose the Agents SDK when your application must own deployment, storage, approvals, and runtime integration. Choose Responses API with a custom loop when ordering, state transitions, and recovery must remain explicit in application code.
How should a consequential action be accepted after recovery?
Use the authoritative external system as the acceptance oracle. Reconcile an immutable operation identifier or idempotency key, verify the observed business state, validate the output against policy and schema constraints, and route ambiguous outcomes to an explicit non-success or approval state. Do not rely solely on the agent session’s terminal status.
Primary documentation
- Introducing the Agents API
- OpenAI Release Notes
- Agents API Overview
- Agents API Architecture
- Sandbox Lifecycle
- Manage Sessions
- Observability and Usage
- Agent Runtime Comparison
- Agents SDK
- Data Controls
- OpenAI API Pricing
Frequently Asked Questions (FAQ)
Does resumption replay every missed event or interrupted command?
No. Saved session items can help reconstruct application state, but they are not a promise that a disconnected stream replays every event or that a killed command restarts. Inspect the current session, saved items, tool results and environment before deciding what should happen next. The lifecycle documentation explicitly separates reconnecting an executor from recovering its commands and files.
What if the external system committed but the tool response was lost?
Treat the result as unknown until the system of record resolves it. Use an application-owned operation identity to find the corresponding transaction or resource. If the operation supports idempotent retries, retain the same identity for the same logical request. If it does not, a human or a reconciliation process may need to decide the next step. Neither a completed turn nor a model-written success sentence is sufficient evidence.
What should a recovery record contain?
Record the requested operation, actor and tenant, target resource, approved arguments, attempts, returned receipts, and independent acceptance result. The exact storage design depends on the application; a universal dual-entry ledger is not an Agents API requirement. Correlation identifiers should connect session items to business records without copying unnecessary sensitive payloads into every telemetry system.
Does managed session state require a complete rewrite to migrate?
Not necessarily. Replacement effort depends on how much the application delegates and what it preserves independently. Canonical tool contracts, an application-owned task ledger, artifact manifests and reproducible evaluation cases can limit the work. Saved items are useful evidence, but retrieving them is not the same as a documented vendor-neutral session replay contract.