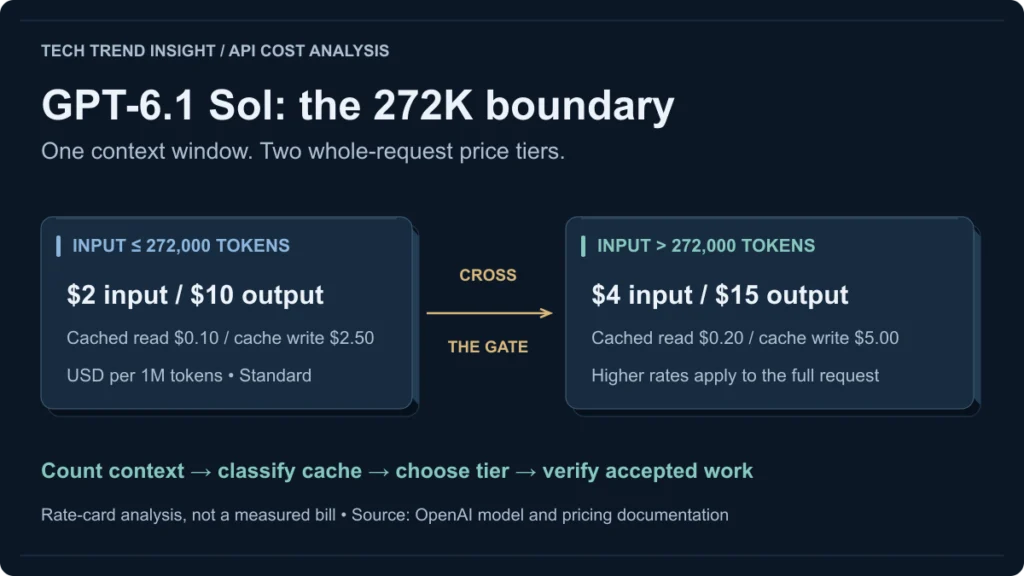
GPT-6.1 Sol’s 272K Pricing Boundary: A Cost Model for Long-Context Agents
GPT-6.1 Sol pricing above 272K input tokens: verified rates, cache-write and read costs, and a six-step framework for long-context agent budgets.
THE ARTICLE ARCHIVE
Explore ideas, explanations, and practical perspectives.
GPT-6.1 Sol pricing above 272K input tokens: verified rates, cache-write and read costs, and a six-step framework for long-context agent budgets.
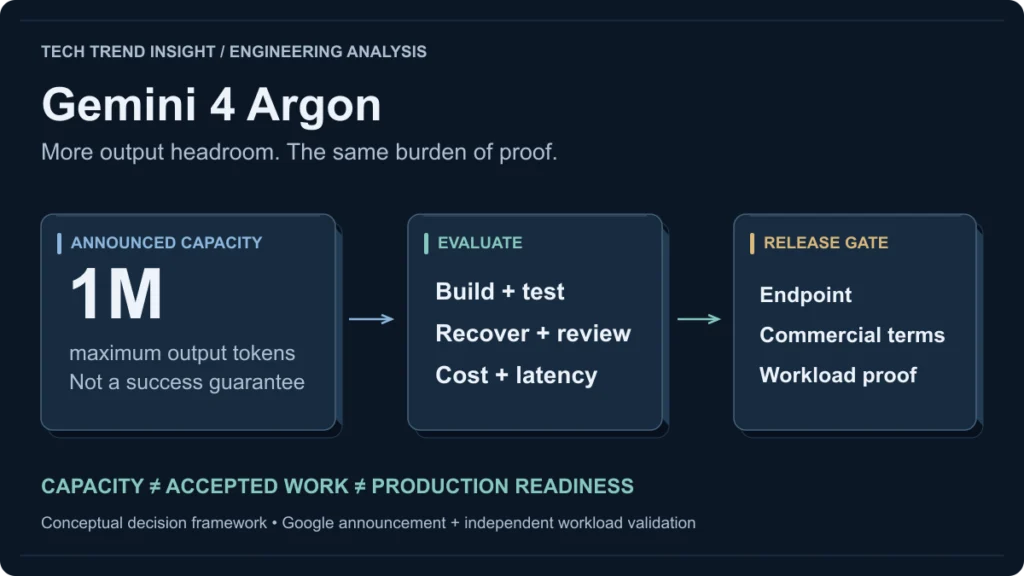
Gemini 4 Argon announces 1M output tokens. Review benchmarks, gated access, pricing and the evidence needed before production migration.
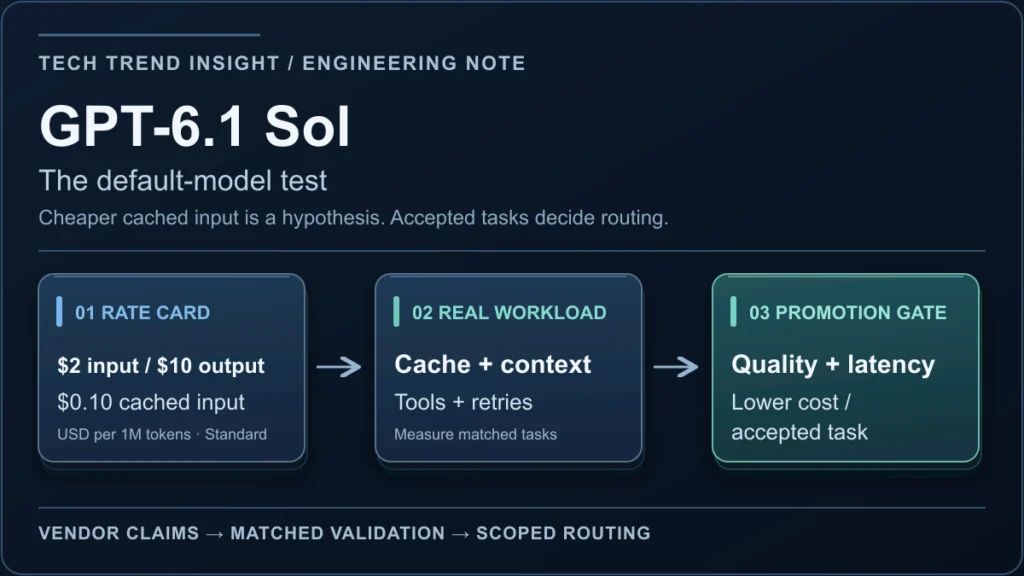
GPT-6.1 Sol halves cached-input cost versus GPT-6 Sol. Review the 272K surcharge, API migration, and cost per accepted task before routing.
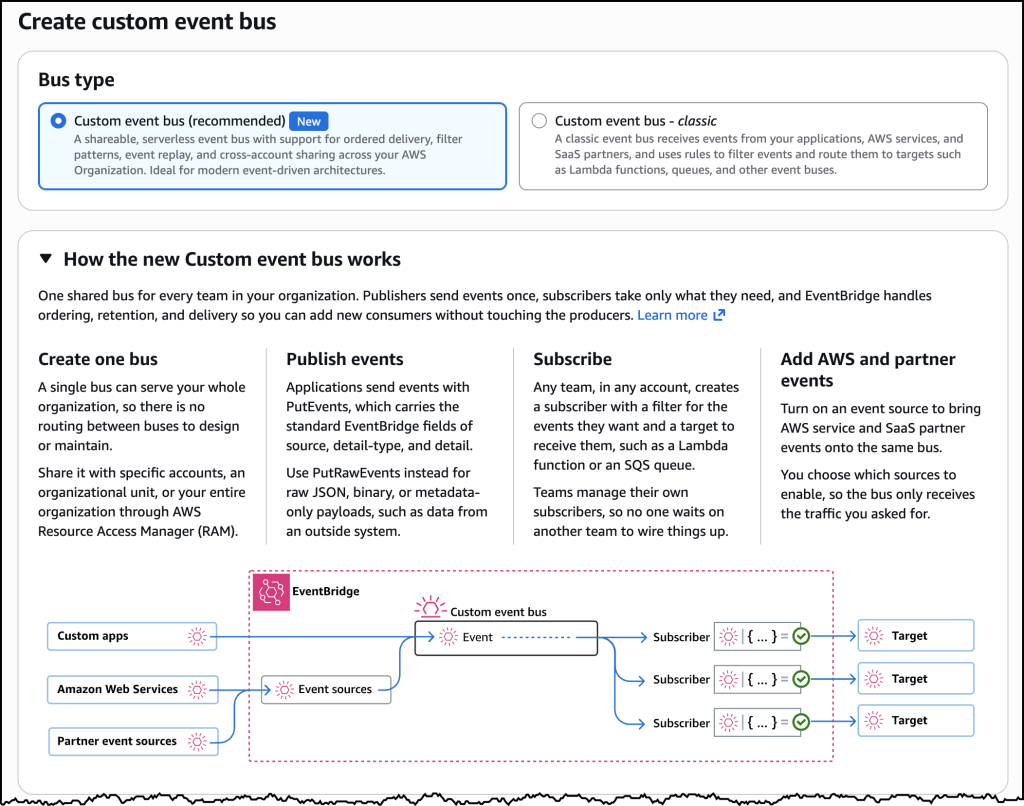
AWS enhanced EventBridge custom buses reduce routing hops but share quotas, policies and recovery risk. A practical architecture review.
GPT-6 Sol and Luna costs explained: token rates, the 272K billing threshold, cache reuse and a budget based on verified successful tasks.
Compare LLM cost per accepted result with provider-aware token accounting, independent validation, and a clearly labeled synthetic worksheet.
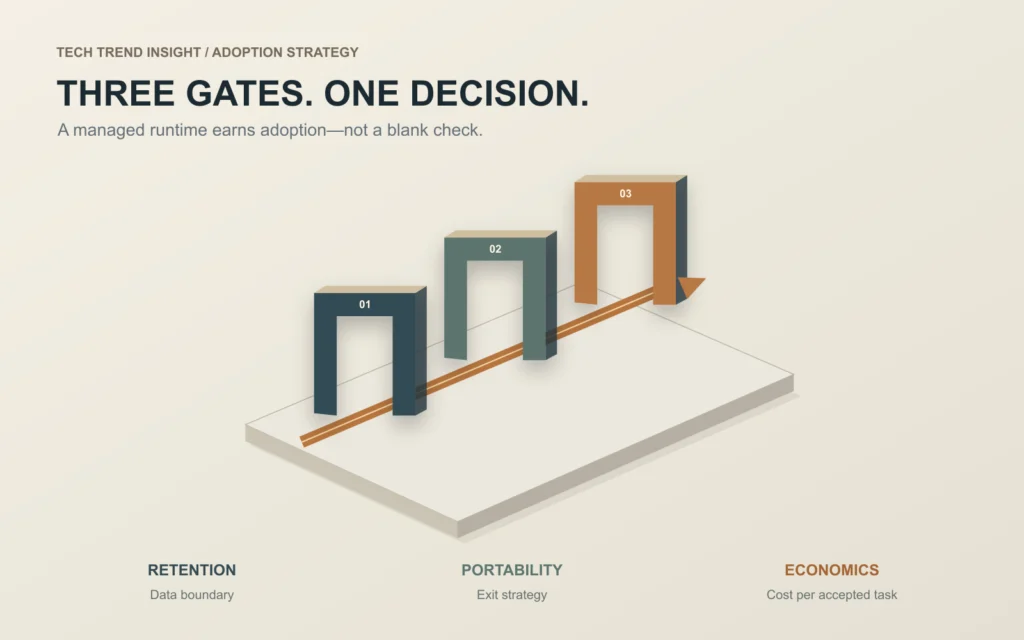
OpenAI's Agents API as a managed control plane: an architectural breakdown of data retention, lock-in, and cost thresholds before pilot adoption.
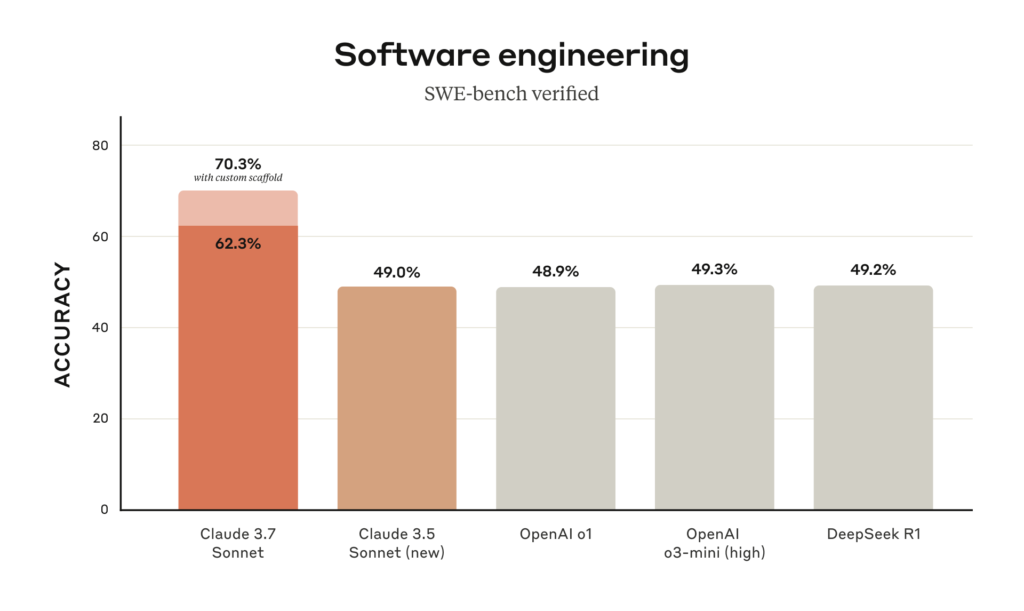
Claude 3.7 Sonnet explained: hybrid reasoning, thinking budgets, benchmark caveats, retirement, and a cost-per-accepted-result example.
Grok 3's 2025 release explained: announcement versus access dates, Colossus context, Think and DeepSearch, and practical evaluation.
How to reliably evaluate LLMs: a reproducible comparison workflow and worksheet for testing accuracy and task completion times.